Machine Learning Applications
Machine learning applications can be divided into several major fields, each with its own unique application scenarios and challenges:
- Computer Vision: Let machines "see" the world
- Natural Language Processing: Let machines "understand" human language
- Recommendation Systems: Personalized content recommendations
- Predictive Analytics: Predict future trends and outcomes
- Anomaly Detection: Discover unusual patterns
Why do these applications need machine learning?
Imagine using traditional programming methods to solve these problems:
- Face recognition: Would require writing countless rules to describe various changes in faces (angle, lighting, expression, etc.)
- Language translation: Would require compiling huge dictionaries and grammar rules for each language pair
- Recommendation systems: Would require manually analyzing each user's preferences and each product's features
Machine learning enables computers to automatically learn these complex patterns from large amounts of data, greatly simplifying the process of problem solving.
Computer Vision Applications
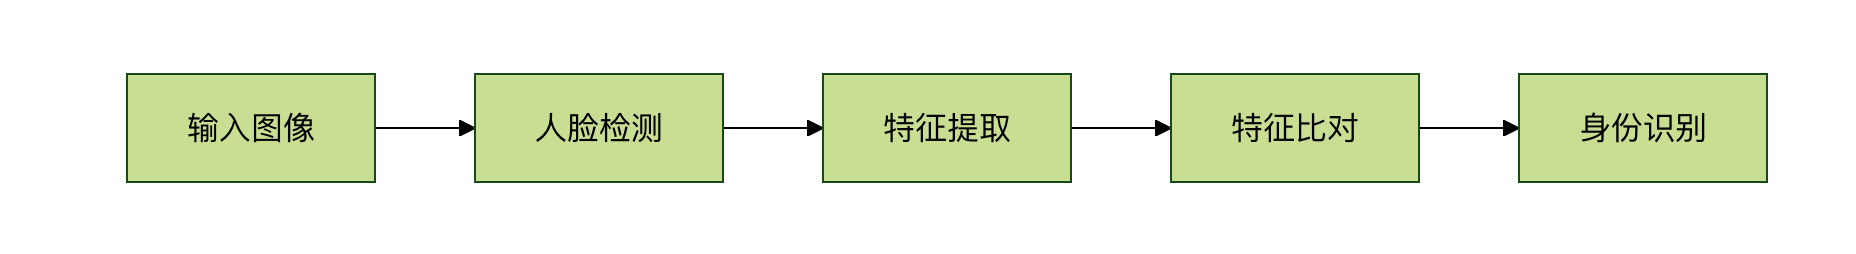
Face Recognition
Application scenarios: Phone unlocking, access control systems, identity verification
How it works:
- Detect face positions in images
- Extract facial features (eye distance, nose shape, etc.)
- Compare with facial features in the database
Autonomous Driving
Application scenarios: Tesla Autopilot, Baidu Apollo, Google Waymo
Core tasks:
- Object detection: Identify vehicles, pedestrians, traffic signs
- Lane detection: Determine lane boundaries
- Path planning: Decide driving routes
Examples
import cv2
import numpy as np
def detect_objects(image):
"""
Detect objects in images (vehicles, pedestrians, traffic signs, etc.)
"""
# 1. Preprocess the image
processed_image = preprocess_image(image)
# 2. Use a trained deep learning model to detect objects
# Here a pretrained YOLO model is used as an example
boxes, classes, scores = yolo_model.detect(processed_image)
# 3. Filter out low-confidence detection results
valid_detections = filter_detections(boxes, classes, scores)
# 4. Draw detection results on the image
result_image = draw_detections(image, valid_detections)
return result_image, valid_detections
# In practice, this is only one component of the entire autonomous driving system
# It also needs to integrate multiple modules such as sensor fusion and path planning
Medical Image Diagnosis
Application scenarios: X-ray analysis, CT scans, pathological slide analysis
Advantages:
- Less fatigue than human doctors
- Can detect subtle changes that are hard for the human eye to notice
- Can quickly process large volumes of images
Natural Language Processing Applications
Intelligent Assistants
Application scenarios: Siri, Xiao Ai, Tmall Genie
Core features:
- Speech recognition: Convert speech to text
- Intent understanding: Understand what the user wants
- Dialogue management: Maintain coherent conversations
Examples
import speech_recognition as sr
from textblob import TextBlob
class SmartAssistant:
def __init__(self):
self.recognizer = sr.Recognizer()
def listen_and_respond(self):
"""Listen to user speech and respond"""
with sr.Microphone() as source:
print("Listening...")
audio = self.recognizer.listen(source)
try:
# 1. Speech recognition
text = self.recognizer.recognize_google(audio, language='zh-CN')
print(f"User said: {text}")
# 2. Intent understanding
intent = self.understand_intent(text)
# 3. Generate response
response = self.generate_response(intent, text)
print(f"Assistant response: {response}")
return response
except sr.UnknownValueError:
return "Sorry, I didn't hear you clearly, please say it again"
def understand_intent(self, text):
"""Understand user intent"""
# Simplified intent recognition
if "weather" in text:
return "weather"
elif "time" in text:
return "time"
elif "joke" in text:
return "joke"
else:
return "unknown"
def generate_response(self, intent, text):
"""Generate response based on intent"""
if intent == "weather":
return "It's sunny today, 25 degrees"
elif intent == "time":
from datetime import datetime
return f"The current time is {datetime.now().strftime('%H:%M')}"
elif intent == "joke":
return "Why do programmers like the dark? Because there are no bugs!"
else:
return "Sorry, I'm still learning and cannot understand this question"
# Usage example
assistant = SmartAssistant()
# assistant.listen_and_respond() # Uncomment when actually running
Machine Translation
Application scenarios: Google Translate, Baidu Translate, Youdao Translate
How it works:
- Encode source language text into numerical representations
- Learn mapping relationships between languages through neural networks
- Decode into target language text
Sentiment Analysis
Application scenarios: Product review analysis, social media monitoring, customer feedback processing
Examples
from textblob import TextBlob
import jieba
def analyze_sentiment_chinese(text):
"""
Chinese sentiment analysis example
"""
# Using jieba for word segmentation
words = jieba.cut(text)
word_list = " ".join(words)
# Simplified here; real applications require dedicated Chinese sentiment analysis models
# Can use libraries like SnowNLP, BERT-Chinese, etc.
# Simulate sentiment analysis results
positive_words = ["good", "great", "like", "satisfied", "recommend"]
negative_words = ["poor", "bad", "hate", "disappointed", "not recommended"]
pos_count = sum(1 for word in positive_words if word in text)
neg_count = sum(1 for word in negative_words if word in text)
if pos_count > neg_count:
return "positive sentiment"
elif neg_count > pos_count:
return "negative sentiment"
else:
return "neutral sentiment"
# Test examples
reviews = [
"This product is really great, I really like it!",
"The quality is too poor, completely not worth buying.",
"It's okay, nothing special."
]
for review in reviews:
sentiment = analyze_sentiment_chinese(review)
print(f"Review: {review}")
print(f"Sentiment: {sentiment}")
print("---")
Recommendation System Applications
E-commerce Recommendations
Application scenarios: Taobao product recommendations, Amazon recommendations
Recommendation strategies:
- Collaborative filtering: Recommend based on similarity of user behavior
- Content-based recommendation: Recommend based on similarity of product features
- Hybrid recommendation: Combine multiple strategies
Examples
import numpy as np
# User-item rating matrix (rows are users, columns are items)
ratings = np.array([
[5, 3, 0, 1], # User 1 ratings for items 1, 2, 4
[4, 0, 0, 1], # User 2 ratings for items 1, 4
[1, 1, 0, 5], # User 3 ratings for items 1, 2, 4
[1, 0, 0, 4], # User 4 ratings for items 1, 4
[0, 1, 5, 4], # User 5 ratings for items 2, 3, 4
])
def user_similarity(user1, user2):
"""Compute similarity between two users (cosine similarity)"""
# Find items that both users have rated
common_items = np.where((user1 > 0) & (user2 > 0))[0]
if len(common_items) == 0:
return 0
# Compute cosine similarity
user1_ratings = user1[common_items]
user2_ratings = user2[common_items]
dot_product = np.dot(user1_ratings, user2_ratings)
norm1 = np.linalg.norm(user1_ratings)
norm2 = np.linalg.norm(user2_ratings)
if norm1 == 0 or norm2 == 0:
return 0
return dot_product / (norm1 * norm2)
def recommend_items(user_id, ratings_matrix, k=2):
"""Recommend items for a specified user"""
user_ratings = ratings_matrix[user_id]
# Compute similarities between this user and other users
similarities = []
for i, other_user in enumerate(ratings_matrix):
if i != user_id:
sim = user_similarity(user_ratings, other_user)
similarities.append((i, sim))
# Sort by similarity
similarities.sort(key=lambda x: x[1], reverse=True)
# Find items not rated by the user
unrated_items = np.where(user_ratings == 0)[0]
# Predict the user's ratings for unrated items
predictions = []
for item_id in unrated_items:
weighted_sum = 0
similarity_sum = 0
for similar_user_id, similarity in similarities[:k]:
if similarity > 0 and ratings_matrix[similar_user_id][item_id] > 0:
weighted_sum += similarity * ratings_matrix[similar_user_id][item_id]
similarity_sum += similarity
if similarity_sum > 0:
predicted_rating = weighted_sum / similarity_sum
predictions.append((item_id, predicted_rating))
# Sort by predicted rating
predictions.sort(key=lambda x: x[1], reverse=True)
return predictions[:3] # Return the top 3 recommendations
# Recommend items for user 0
user_id = 0
recommendations = recommend_items(user_id, ratings)
print(f"Recommended items for user {user_id}:")
for item_id, predicted_rating in recommendations:
print(f"Item {item_id + 1}, predicted rating: {predicted_rating:.2f}")
Video Recommendations
Application scenarios: Douyin, YouTube, Netflix
Features:
- Real-time recommendation (adjusted based on user's current behavior)
- Multimodal data (video content, user behavior, time, etc.)
- Cold start problem handling
Predictive Analytics Applications
Financial Risk Control
Application scenarios: Credit card fraud detection, loan approval
Examples
import numpy as np
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split
# Simulate transaction data
# Features: transaction amount, transaction time, merchant type, location, etc.
# Labels: 0=normal, 1=fraud
np.random.seed(42)
# Generate simulated data
n_samples = 1000
n_features = 4
# Normal transactions
normal_transactions = np.random.normal(loc=[100, 14, 2, 3], scale=[50, 4, 1, 1],
size=(int(n_samples * 0.95), n_features))
# Fraudulent transactions (usually abnormal amounts, abnormal times, etc.)
fraud_transactions = np.random.normal(loc=[500, 3, 4, 1], scale=[200, 2, 1, 0.5],
size=(int(n_samples * 0.05), n_features))
# Merge data and add labels
X = np.vstack([normal_transactions, fraud_transactions])
y = np.hstack([np.zeros(len(normal_transactions)), np.ones(len(fraud_transactions))])
# Split training and test sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Train random forest model
model = RandomForestClassifier(n_estimators=100, random_state=42)
model.fit(X_train, y_train)
# Evaluate the model
accuracy = model.score(X_test, y_test)
print(f"Model accuracy: {accuracy:.2f}")
# Predict new transactions
new_transaction = np.array([[450, 2, 4, 1]]) # Abnormal transaction
fraud_probability = model.predict_proba(new_transaction)[0][1]
print(f"Probability that the new transaction is fraud: {fraud_probability:.2f}")
if fraud_probability > 0.5:
print("Warning: Suspicious transaction detected!")
else:
print("Transaction is normal.")
Stock Price Prediction
Application scenarios: Quantitative trading, investment decisions
Challenges:
- High market noise
- Non-stationary time series
- Affected by multiple factors
Anomaly Detection Applications
Cybersecurity
Application scenarios: Intrusion detection, malware identification
How it works:
- Learn normal network traffic patterns
- Detect behaviors that deviate from normal patterns
- Trigger alerts or block
Industrial Quality Inspection
Application scenarios: Product defect detection, equipment failure prediction
Examples
import numpy as np
from sklearn.ensemble import IsolationForest
import matplotlib.pyplot as plt
# Simulate sensor data (normal data + a few anomalies)
np.random.seed(42)
# Normal data: sensor readings when the device is operating normally
normal_data = np.random.normal(loc=10, scale=1, size=(200, 2))
# Anomalous data: sensor readings when the device fails
anomaly_data = np.random.normal(loc=[15, 5], scale=[1, 1], size=(10, 2))
# Merge data
all_data = np.vstack([normal_data, anomaly_data])
# Use Isolation Forest for anomaly detection
model = IsolationForest(contamination=0.05, random_state=42)
predictions = model.fit_predict(all_data)
# Visualize results
plt.figure(figsize=(10, 6))
normal_points = all_data[predictions == 1]
anomaly_points = all_data[predictions == -1]
plt.scatter(normal_points[:, 0], normal_points[:, 1],
c='blue', label='Normal data')
plt.scatter(anomaly_points[:, 0], anomaly_points[:, 1],
c='red', label='Anomalous data')
plt.xlabel('Sensor 1 reading')
plt.ylabel('Sensor 2 reading')
plt.title('Device operating status anomaly detection')
plt.legend()
plt.grid(True)
plt.show()
print(f"Detected {len(anomaly_points)} anomaly points")