TensorFlow Data Processing and Pipelines
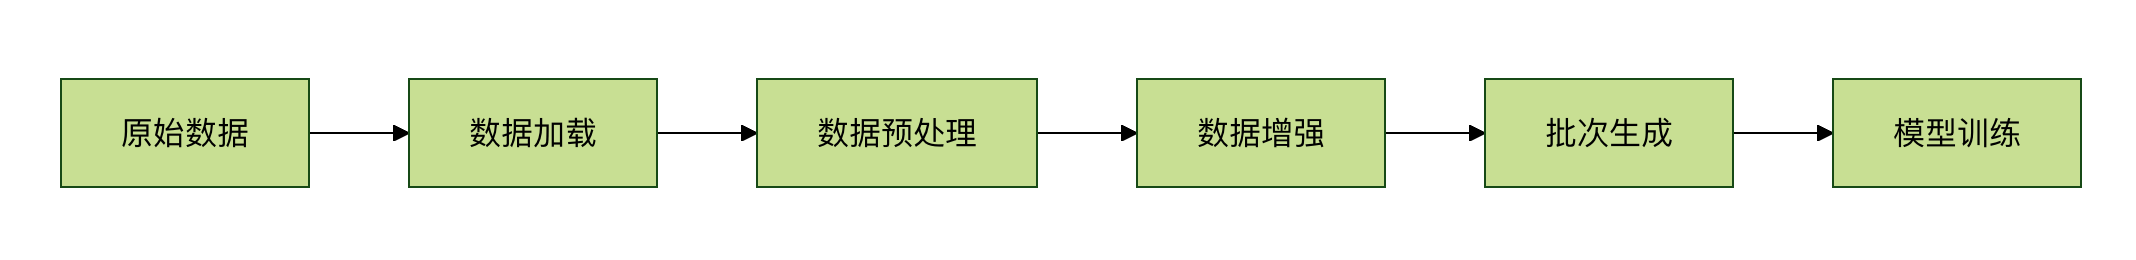
The TensorFlow data processing pipeline is a key part of the machine learning workflow. It is responsible for efficiently loading, preprocessing, and transferring data to the model.
Compared with traditional direct data loading methods, the TensorFlow pipeline offers three major advantages:
- Performance optimization: Reduce I/O bottlenecks through parallelization and prefetching
- Memory efficiency: Avoid loading all data into memory at once
- Clean code: Decouple data processing logic from model code
Core Concepts
Dataset API
The TensorFlow Dataset API is the core tool for building data pipelines. It provides various data source interfaces and transformation operations:
Example
# Create Dataset from memory
data = tf.data.Dataset.from_tensor_slices([1, 2, 3])
# Create from text file
text_data = tf.data.TextLineDataset(["file1.txt", "file2.txt"])
# Create from TFRecord
tfrecord_data = tf.data.TFRecordDataset("data.tfrecord")
Data Preprocessing Techniques
Common preprocessing operations include:
- Standardization:
(x - mean) / std - Normalization:
(x - min) / (max - min) - One-hot encoding:
tf.one_hot() - Padding/Truncation:
tf.keras.preprocessing.sequence.pad_sequences
Pipeline Building Steps
1. Data Loading
Choose the appropriate loading method based on the data source:
Example
def load_image(path):
img = tf.io.read_file(path)
img = tf.image.decode_jpeg(img, channels=3)
return tf.image.resize(img, [256, 256])
image_dataset = tf.data.Dataset.list_files("images/*.jpg")
image_dataset = image_dataset.map(load_image)
2. Data Preprocessing
Usemap()method to apply the preprocessing function:
Example
return image / 255.0 # Normalize to 0-1 range
normalized_dataset = image_dataset.map(normalize)
3. Data Augmentation
Common augmentation techniques used during training:
Example
image = tf.image.random_flip_left_right(image)
image = tf.image.random_brightness(image, max_delta=0.2)
return image
augmented_dataset = normalized_dataset.map(augment)
4. Batch Processing
Configure batch size and prefetching:
Example
train_dataset = augmented_dataset.batch(BATCH_SIZE)
train_dataset = train_dataset.prefetch(tf.data.AUTOTUNE)
Advanced Optimization Techniques
Performance Optimization Strategies
| Strategy | Method | Effect |
|---|---|---|
| Parallelization | num_parallel_calls=tf.data.AUTOTUNE |
Speed up data loading |
| Prefetching | prefetch(buffer_size=tf.data.AUTOTUNE) |
Reduce waiting time |
| Caching | cache() |
Avoid repeated computation |
Example
.map(load_image, num_parallel_calls=tf.data.AUTOTUNE)
.cache()
.map(augment, num_parallel_calls=tf.data.AUTOTUNE)
.batch(32)
.prefetch(tf.data.AUTOTUNE))
Memory Management
When handling large datasets:
- Use
TFRecordformat to store data - Sharded processing:
dataset.shard(num_shards, index) - Streaming processing: avoid
cache()large files
Practical Example: Image Classification Pipeline
Complete image classification data processing flow:
Example
# 1. Load data
dataset = tf.data.Dataset.list_files(f"{image_dir}/*/*.jpg")
# 2. Parse and preprocess
def process_path(file_path):
label = tf.strings.split(file_path, os.sep)[-2]
image = load_image(file_path)
return image, label
dataset = dataset.map(process_path, num_parallel_calls=tf.data.AUTOTUNE)
# 3. Augmentation during training
if is_training:
dataset = dataset.map(
lambda x, y: (augment(x), y),
num_parallel_calls=tf.data.AUTOTUNE
)
# 4. Optimize configuration
dataset = dataset.batch(batch_size)
dataset = dataset.prefetch(tf.data.AUTOTUNE)
return dataset
Common Problems and Solutions
Performance Bottleneck Troubleshooting
Low CPU utilization
- Increase
num_parallel_calls - Use
interleave()Parallelize I/O
- Increase
Low GPU utilization
- Increase
prefetch_buffer_size - Check whether the batch size is appropriate
- Increase
Data Skew Handling
Example
dataset = dataset.apply(
tf.data.experimental.sample_from_datasets(
[class1_ds, class2_ds],
weights=[0.7, 0.3]
)
)
Best Practice Recommendations
1. Pipeline design principles
- Place time-consuming operations in early stages
- Keep preprocessing operations deterministic
- Disable data augmentation for the validation set
2. Monitoring tools
Example
tf.data.experimental.latency_stats()
3. Version compatibility
- For TF 2.x, it is recommended to use
tf.dataAPI - Avoid mixing
feed_dictapproaches
By properly designing the TensorFlow data pipeline, you can increase training speed by 2-5 times while keeping the code clean and maintainable.
Other Extensions